Multi-Region Telecom Architecture: Designing Failover Without Split-Brain
A telecom platform can operate reliably for months and still fail when an entire region becomes unavailable. A cloud region may experience a networking incident, a database cluster may become unreachable, or a regional dependency may prevent services from communicating with one another. In these situations, running the application in another region is only the beginning of the recovery process.
The difficult question is whether the surviving region can continue processing subscriber operations, provisioning requests, and billing transactions without creating conflicting state.
Multi-region architecture introduces a fundamental trade-off between availability, consistency, latency, and operational complexity. For telecom platforms, these trade-offs cannot be treated as infrastructure decisions alone. They affect how the system handles subscriber identity, transaction ownership, usage records, and recovery after an interruption.
Why Running Two Regions Is Not Enough
A common architecture places application services in two cloud regions, with each region capable of running the same workloads. Traffic can be redirected if one region becomes unavailable, giving the platform an alternative location from which to operate.
However, application redundancy does not automatically provide data redundancy or transaction safety.
Suppose Region A and Region B both maintain subscriber state. Region A processes a plan change while Region B experiences a replication delay. If traffic shifts to Region B before the update has arrived, the second region may read an older version of the subscriber record. A subsequent operation could then overwrite newer information or produce a decision based on stale state.
A similar problem can occur with billing. If both regions believe they are responsible for processing the same usage event, the platform may create duplicate financial records unless the processing model prevents it.
A multi-region system must therefore define more than where its services run. It must establish which region owns a particular operation, how data changes become visible elsewhere, and what happens when the regions cannot communicate.
Active-Passive Versus Active-Active
In an active-passive architecture, one region handles normal production traffic while another remains available for recovery. The standby region may continuously receive replicated data and run essential services, but it does not ordinarily own the same production workloads.
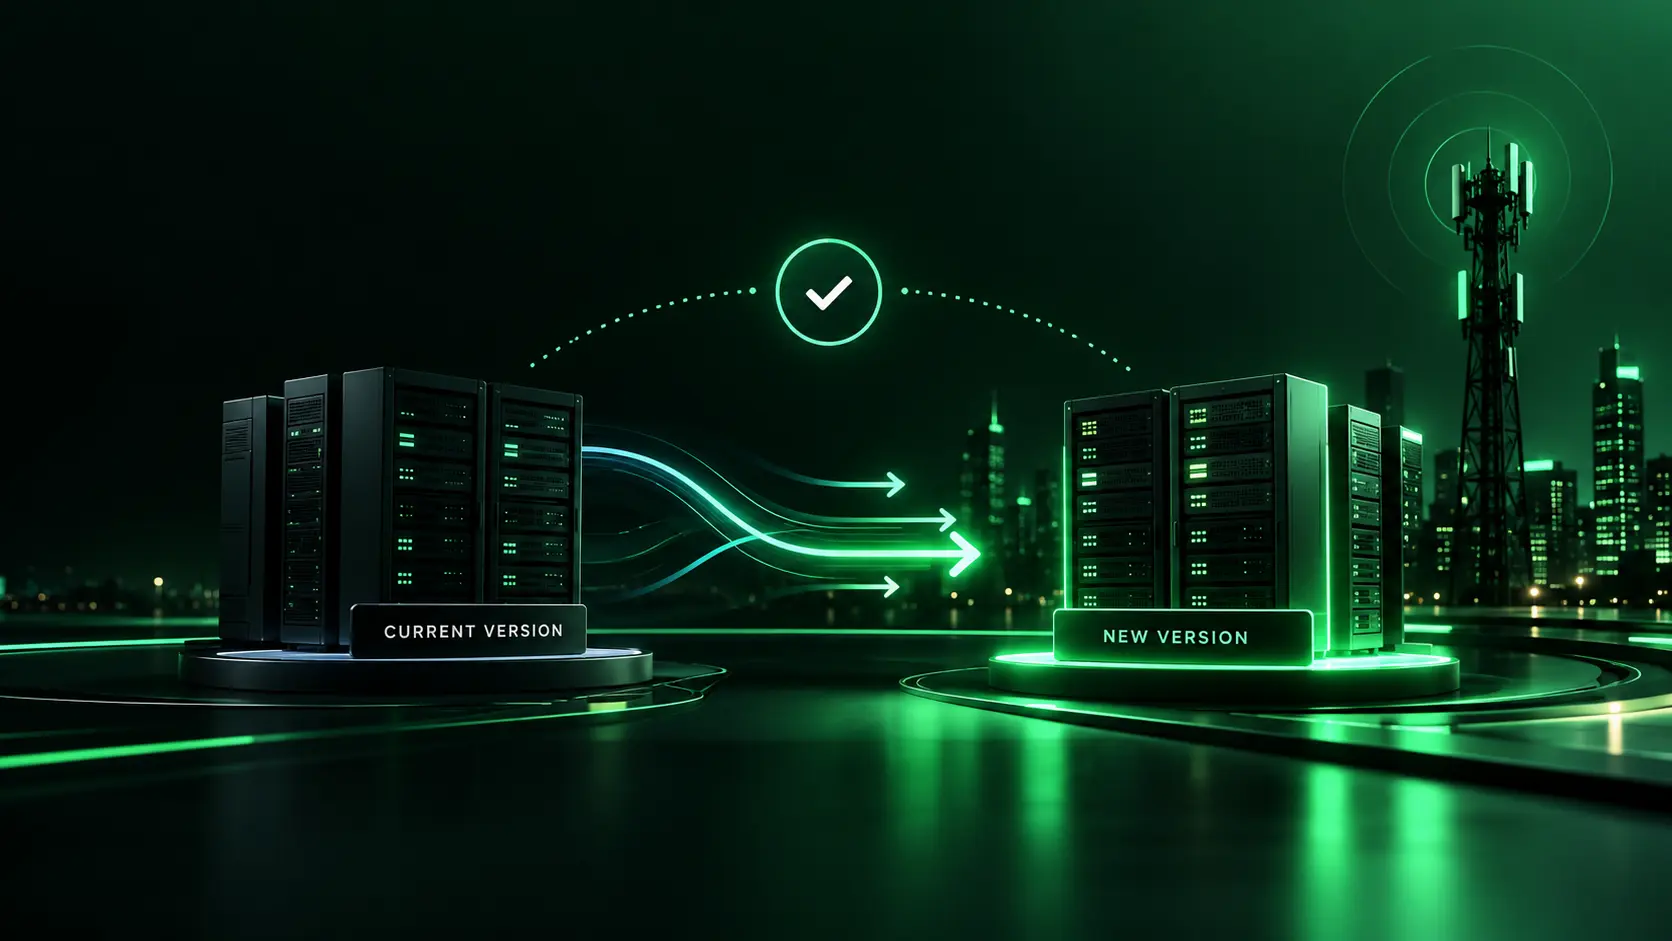
This arrangement simplifies some operational decisions because there is a clear primary region. When a failure occurs, the platform can promote the standby region and redirect traffic. The main challenges are replication lag, promotion procedures, dependency readiness, and the time required to restore normal operations.
An active-active architecture allows both regions to serve production traffic simultaneously. It can improve regional capacity utilization and reduce dependence on a single location, but it also introduces more complex coordination requirements.
If two regions can update the same logical record independently, the platform needs a strategy for handling concurrent writes. If both can initiate the same business operation, it needs a mechanism to prevent duplicate execution. If replication is asynchronous, each region must also account for the possibility that its view of the data is temporarily incomplete.
Neither model is universally superior. The right choice depends on the workload, acceptable recovery time, consistency requirements, infrastructure costs, and the consequences of conflicting operations.
Split-Brain: The Failure That Creates Two Authorities
Split-brain occurs when parts of a distributed system lose contact with one another but continue operating as though they have authority over the same resource.
Imagine two telecom regions that normally coordinate access to a subscriber's account. A network partition prevents communication between them. Each region remains healthy from its local perspective, and both continue accepting plan changes.
When connectivity returns, the platform may discover that the same account was modified independently in both regions. One update may overwrite another, or the resulting state may not correspond to any valid sequence of business operations.
The problem is not simply that data replication was delayed. It is that two components were allowed to make conflicting decisions without a reliable ownership rule.
A safer architecture establishes explicit authority over operations. This may involve a single write owner for a particular dataset, a consensus-backed coordination mechanism, or partitioning ownership so that different regions control different sets of records.
The important requirement is that losing communication must not automatically grant every isolated region permission to act as the authoritative writer.
Fencing Tokens and Lease Expiration
Distributed locks and leases can help coordinate ownership, but they require careful implementation.
A lease grants a process temporary authority over a resource. When the lease expires, another process may acquire ownership. However, the original process might still be running because of a network delay, a long pause, or a failure to detect the lease expiration.
If that process continues writing, two processes may effectively act as owners.
Fencing tokens address this problem by assigning a monotonically increasing token whenever ownership changes. A downstream resource checks the token and rejects operations from an older owner after a newer token has been issued.
For example, a billing-processing partition might be assigned to a worker holding token 42. If another worker later acquires ownership with token 43, the database or other protected resource should reject stale writes carrying token 42.
This protection works only when the resource receiving the write validates the token. A lease maintained solely in application memory cannot guarantee that an old owner will stop acting after losing authority.
For critical telecom workflows, ownership rules must therefore be enforced at the point where state is changed.
Replication Lag and the Consistency Problem
Cross-region replication often introduces latency. Synchronous replication can provide stronger guarantees about when a write is acknowledged, but it may increase request latency and reduce availability when the remote region cannot be reached.
Asynchronous replication generally allows the primary region to acknowledge writes sooner, but the secondary region may temporarily contain stale data.
This distinction matters differently across telecom workloads.
A dashboard displaying historical usage may tolerate some replication delay. A subscriber balance check, plan eligibility decision, or operation that depends on the latest account state may require stronger consistency.
The architecture should classify data according to its business requirements instead of applying one consistency policy to every table and service.
It should also define what happens during regional isolation. If a region cannot confirm the latest state required for a transaction, the system may need to reject the operation, route it to the authoritative region, or allow only a restricted set of operations that remain safe under the available information.
The correct choice depends on the consequences of accepting stale data.
Preventing Duplicate Billing and Usage Processing
Telecom billing introduces a particularly important recovery requirement: a regional failover must not turn previously processed events into duplicate financial transactions.
Suppose Region A consumes a usage event and records a charge, but the confirmation has not yet replicated to Region B. Region A then becomes unavailable. Region B receives the same event and cannot immediately determine whether the original charge was committed.
Simply checking whether the event appears in a local processing table is insufficient if that table is behind.
A robust design uses stable business identifiers, durable transaction records, idempotent processing, and an authoritative mechanism for deciding whether an operation has already been committed. Where financial state is involved, the record of the transaction and its processing status must be coordinated carefully.
The architecture should also distinguish between an event being received, an event being processed, and a transaction being durably committed. Those states are not interchangeable.
Even with these safeguards, failover behavior needs explicit testing. Replication delays and ambiguous transaction outcomes are precisely the conditions that ordinary success-path testing tends to miss.
Designing a Controlled Regional Failover
Regional failover should be treated as a controlled transition rather than a simple traffic-routing change.
The platform first needs reliable signals that distinguish a genuine regional failure from a temporary connectivity problem. It must then determine whether the surviving region has sufficient capacity and whether its dependencies are ready.
Before accepting writes, the promoted region may need to establish authoritative ownership, verify database recovery state, and confirm that required services can communicate with one another. Traffic can then be shifted according to a defined policy.
Recovery also requires a plan for the original region. When it becomes available again, it should not automatically resume writing against potentially outdated state. The system must establish whether it is still authoritative, reconcile any permitted local work, and rejoin the normal topology safely.
This process should be automated where possible, but automation must be based on clear state transitions and ownership rules. A fast failover mechanism that promotes two writers simultaneously can create a more serious incident than the original outage.
Test the Failure Modes, Not Just the Failover Button
A meaningful multi-region test should go beyond shutting down a service and confirming that traffic moves elsewhere.
Engineers should simulate network partitions, delayed replication, failed lease renewal, interrupted transactions, and a region returning after an extended outage. Tests should examine whether stale writers can still commit changes, whether events are processed more than once, and whether the surviving region can sustain the expected workload.
Recovery time and recovery point objectives should be measured against actual behavior. The first describes how quickly service should be restored; the second describes the acceptable amount of data loss or recovery-point lag. Both need to reflect the requirements of individual workloads.
The most useful tests verify business correctness, not simply service availability. A region that responds to requests but produces inconsistent subscriber or billing state has not recovered successfully.
Final Thoughts
Multi-region telecom architecture is fundamentally a problem of authority, consistency, and recovery. Deploying services in two regions can improve resilience, but it does not by itself prevent conflicting writes, duplicate processing, or unsafe failover.
A dependable design defines ownership explicitly, accounts for replication lag, protects state changes against stale writers, and makes recovery behavior predictable. It also recognizes that different workloads have different consistency requirements.
The goal is not to make every region independently authoritative at all times. It is to ensure that when a region fails, the remaining system can continue only the operations it can perform safely—and restore broader operation without compromising data correctness.
About the author
- TelcoEdge – A cloud-native BSS for telecoms. Helping operators launch faster, scale smarter & grow with AI, automation & cross-border billing. 🌐 telcoedge.com
Comments
Join the discussionNo comments yet. Be the first to comment.